Self-directed
Low-Latency Order Book
market microstructure
systems
Project overview
Cache-resident C++ matching engine
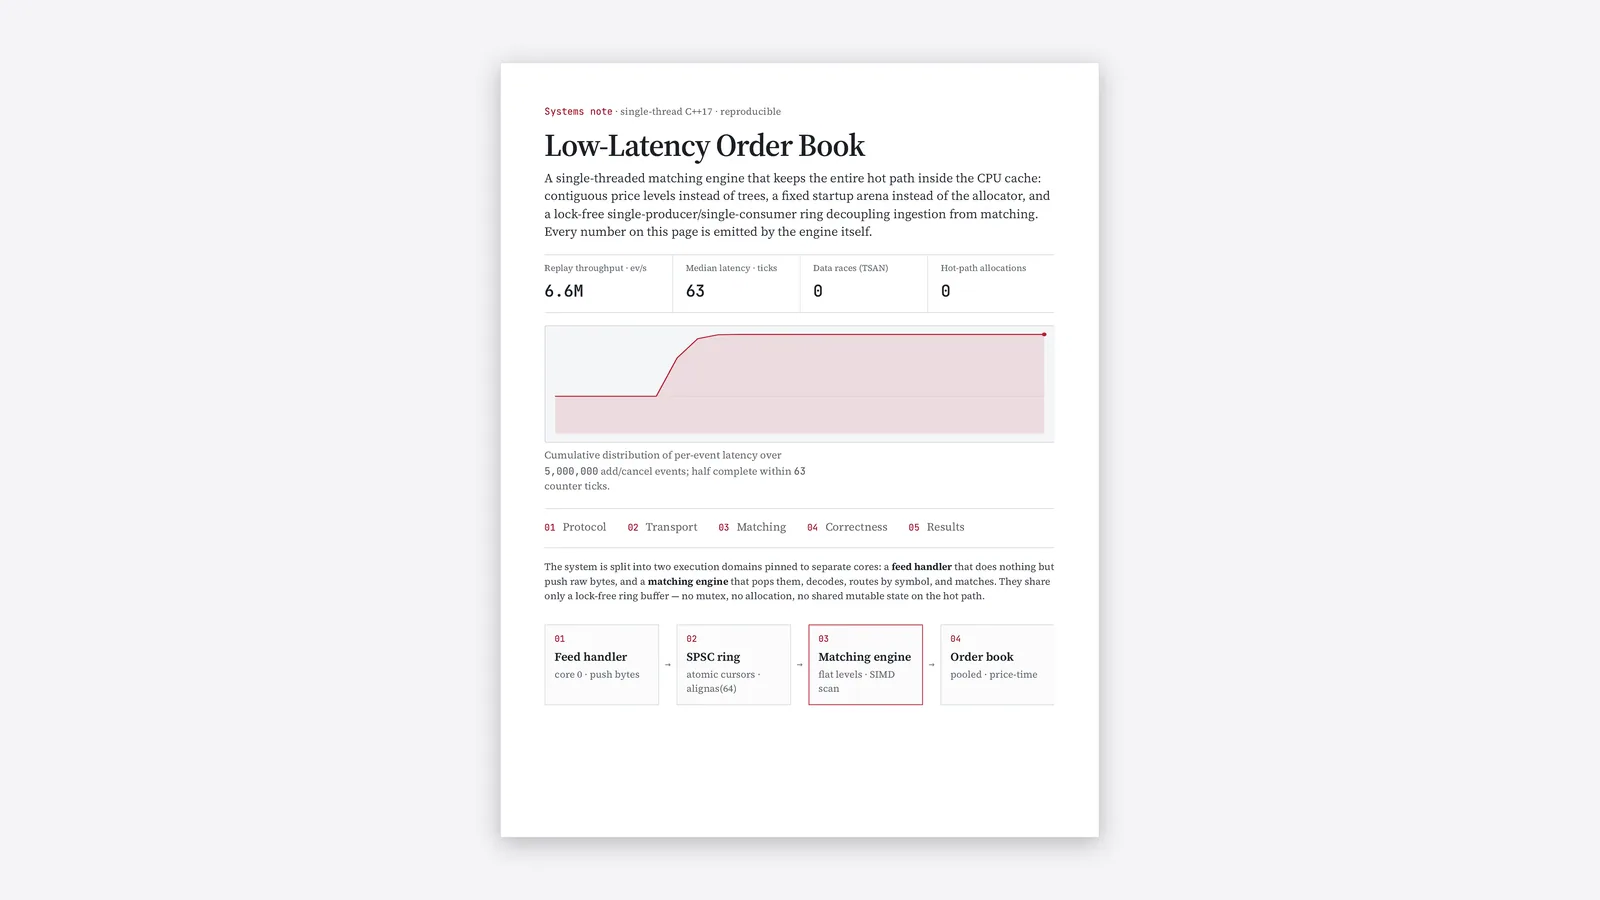
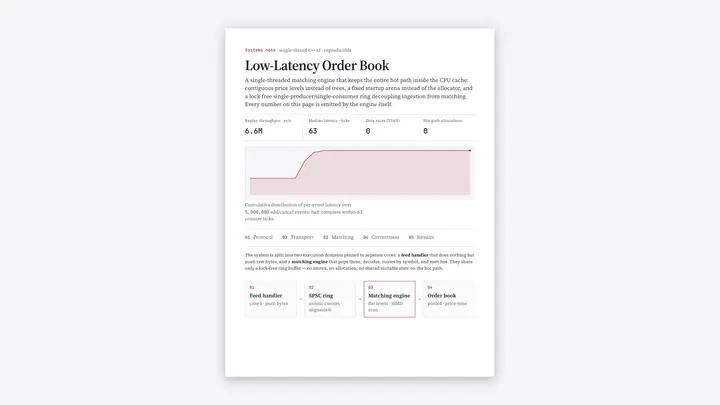
A single-threaded limit order book and matching engine that keeps the entire hot path inside the CPU cache — contiguous price levels instead of trees, with a lock-free ring decoupling ingestion from matching.
Date
2026
Field
Quant
Stack
C++17, SIMD, Lock-free, Make
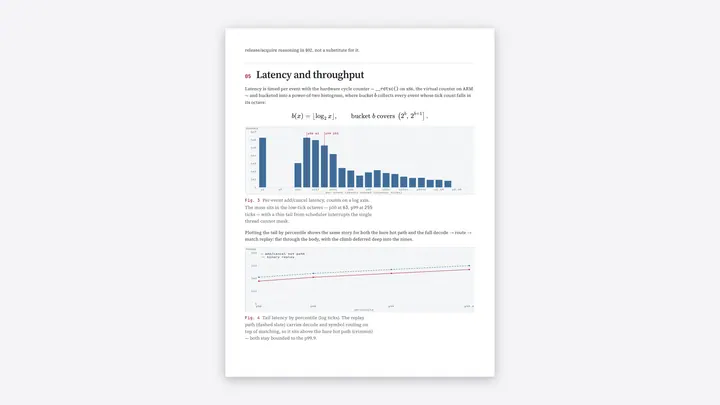
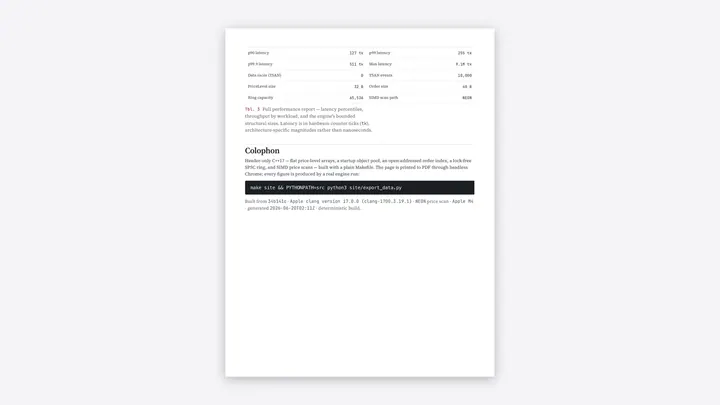
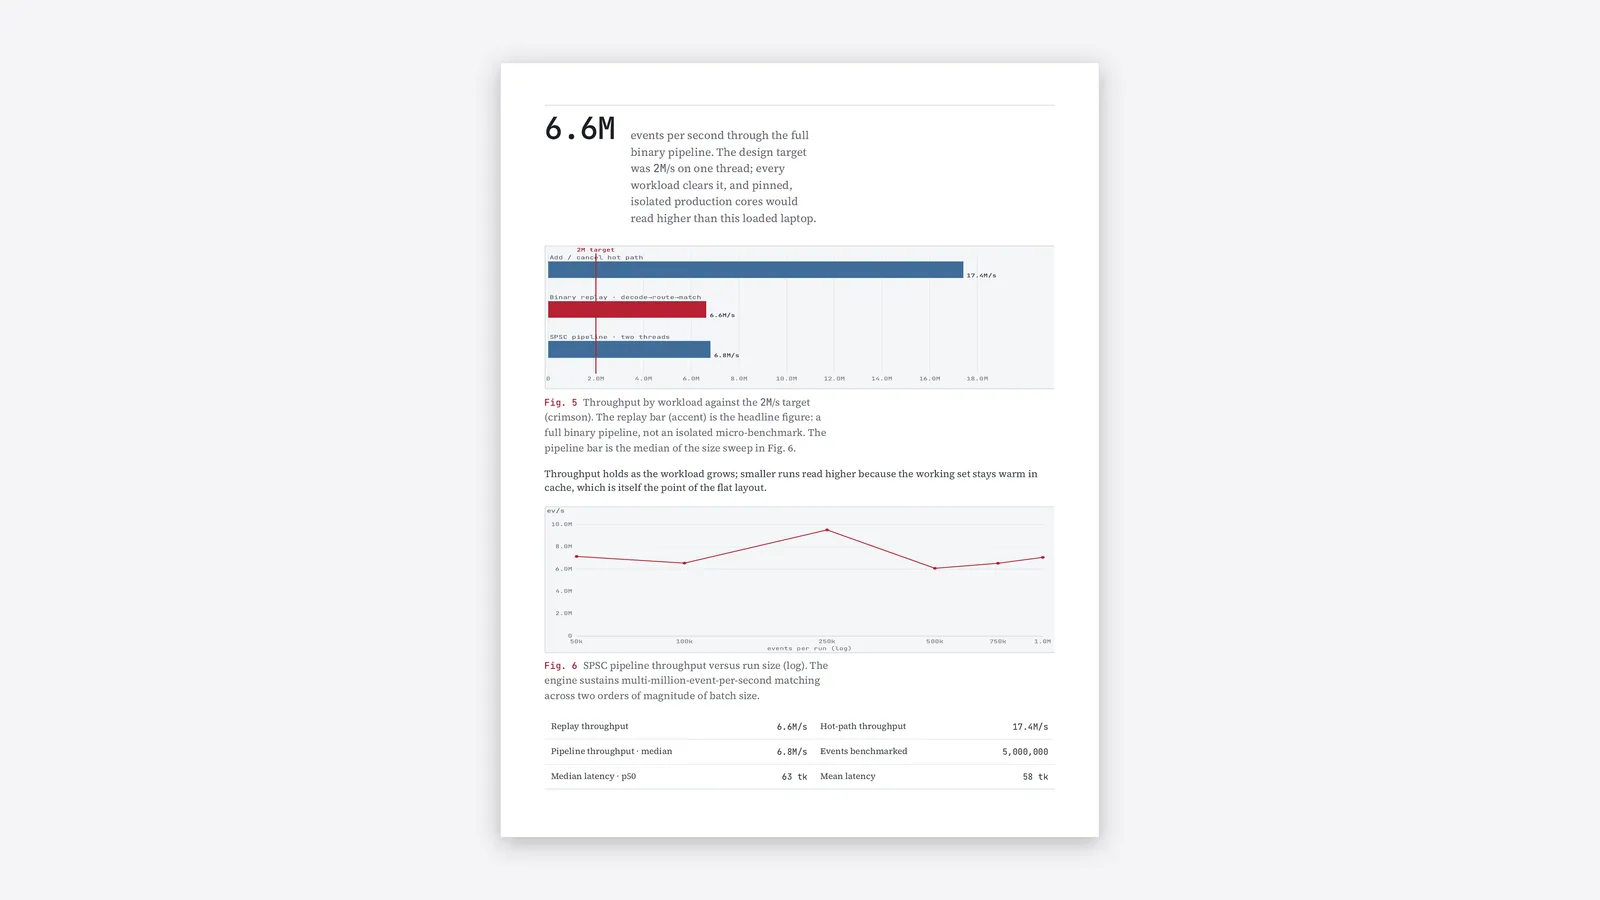
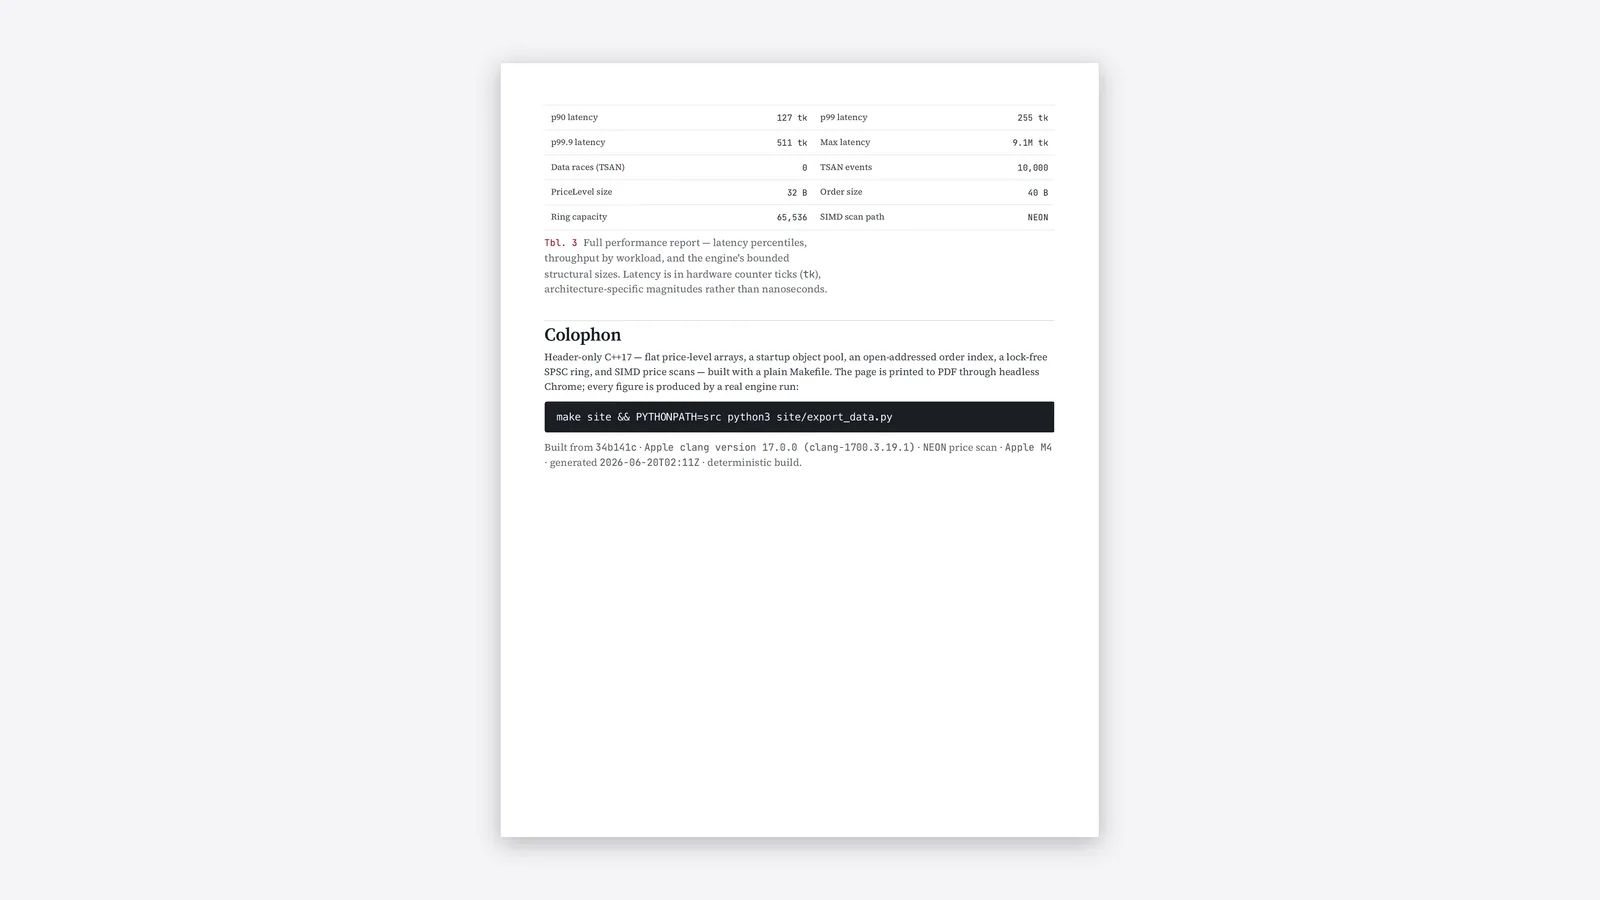
~63-tick median latency
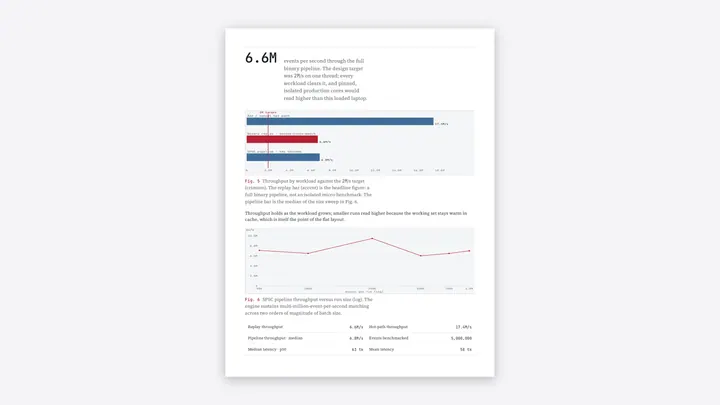
>2M events/s cleared
0 data races (TSan)
Context
An ultra-low-latency single-threaded limit order book in C++17, decoupled from a mock market feed by a lock-free single-producer/single-consumer queue.
Low-Latency Order Book
The hard part
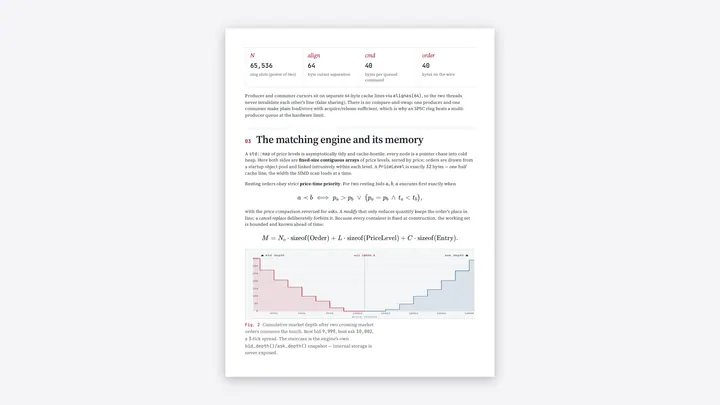
The design exists to demonstrate the systems ideas that matter in production market infrastructure and to be defensible in a quant-systems interview: O(N) on a cache-resident array beats O(1) with a cache miss.
What it took
- Stored bids and asks as flat, sorted, contiguous price-level arrays scanned with AVX2 / NEON SIMD price compares, with intrusive doubly-linked order lists giving price-time priority for free.
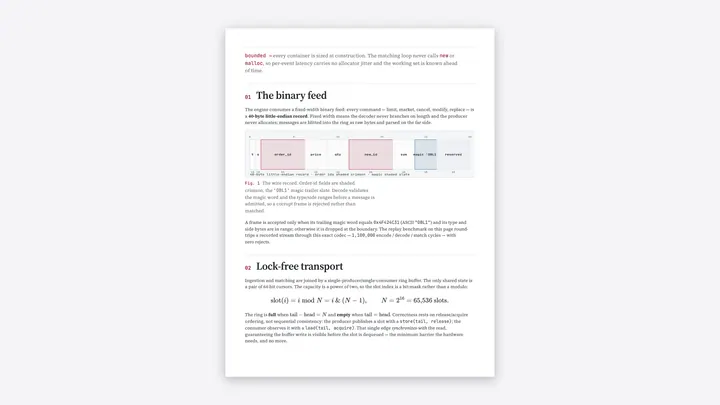
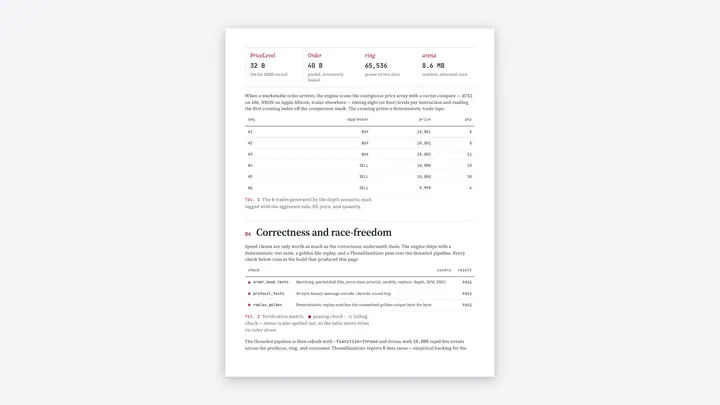
- Eliminated hot-path allocation with a fixed object-pool arena and an open-addressed order index, and joined the feed handler and matching engine across isolated cores by a lock-free SPSC ring using only acquire/release cursors on separate cache lines.
- Validated a fixed-width 40-byte binary protocol on its magic word before matching, measured per-event latency with a hardware cycle counter into a power-of-two histogram, and proved correctness with deterministic golden-file replay plus a clean ThreadSanitizer run.